Qwen3.8-27B 发布,小体积模型进入本地智能时代
👏Smart Yet Small: The Dawn of Local Intelligence
作者分析阿里 Qwen3.8-27B 的发布为何被视为面向开发者的大新闻:阿里 Qwen 开源权重模型过去六个月累计全球下载 30 亿次,覆盖 0.8B 到 80B 多个尺寸,便于开发者本地运行以掌控数据隐私和成本。
When Alibaba released Qwen 3.8-Max, its newest, most powerful flagship open-weight LLM featuring 2.4 trillion parameters, many developers were instead looking forward to the release of its 27B variant instead.
Alibaba’s Qwen open-weight models have accumulated 3 billion global downloads over the past six months. One reason they are so popular in the developer community is that the Chinese tech giant releases small models across every size, from 0.8B to 80B of parameters, meeting developers who want to run models locally.
Running local models gives developers complete control over data privacy and costs. It keeps sensitive data and code on local machines without sharing on public cloud APIs, and replaces pay-per-token API fees for token-heavy agentic workflows with a fixed hardware investment.
A 27B model sits in a sweet spot: it’s small enough to run locally on a well-equipped computer (24~64GB of RAM) with premium consumer-grade GPUs such as Nvidia’s RTX 5090, but smart enough to handle a wide range of real-world tasks. The Qwen 27B series in particular has always been popular, which is why last Friday’s release of Qwen3.8-27B was hailed as massive news for builders.
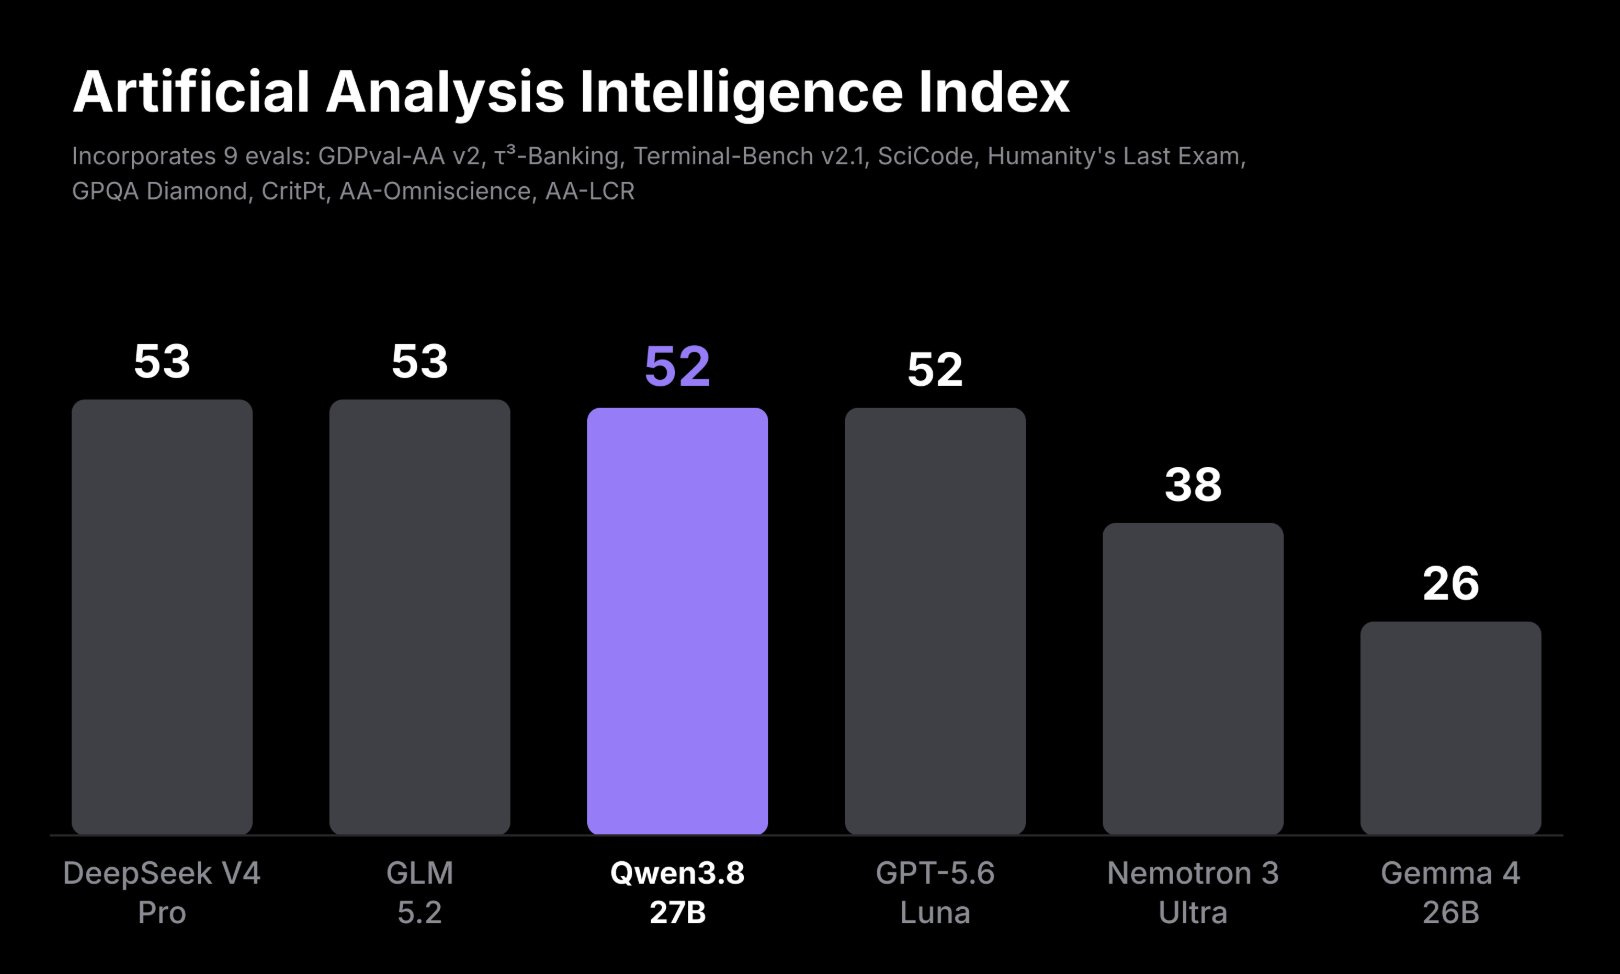
What surprised almost everyone was the benchmark hit: the 27B model scored a staggering 52 on the Artificial Analysis Intelligence Index, making it the smartest model in its size class. It’s on par with GPT-5.6 Luna and Zhipu’s GLM-5.2—which is ~30 times bigger—while outperforming MiniMax-M3 and Thinking Machines’ near-1T inkling model. Qwen3.8-27B is a dense model, not an MoE, meaning it activates all its parameters on every inference run.
来源:Recode China AI · recodechinaai.com